
Route handlers in your application often act as the primary bridge between client interfaces and your database or external APIs. Because they accept raw HTTP requests, they sit directly in the line of fire for credential stuffing, scrapers, and denial of service attempts. You can't just trust that incoming payloads match what your frontend forms sent. It's easy to assume that because a component rendered a specific input structure, the corresponding endpoint will only ever see that same shape. Production traffic doesn't care about your component tree. Bots will hammer your endpoints with malformed JSON, missing headers, and unexpected types until something breaks. You need to implement explicit defenses directly inside each handler before running any business logic.
Ignoring these edge cases turns your backend logs into a graveyard of unhandled exceptions and database constraint violations. Attackers don't use your frontend forms. They write scripts that target your endpoints directly, bypassing every client-side check you spent days writing in React. If you want your application to survive contact with the open internet, every single route handler must treat incoming data as hostile until proven otherwise. This means checking data types at runtime, limiting how fast any single client can hammer your database, and verifying that requests actually originate from the pages you built.
Validating Incoming Payloads With Zod
Never read request.json() and cast the result blindly to a TypeScript interface. TypeScript types evaporate at compile time, leaving your runtime exposed to whatever garbage a client decides to transmit. You need a validation library that enforces runtime schemas and strips out unexpected properties. Zod remains the standard choice for this job because it integrates cleanly into modern Node environments and throws descriptive errors when data fails validation.
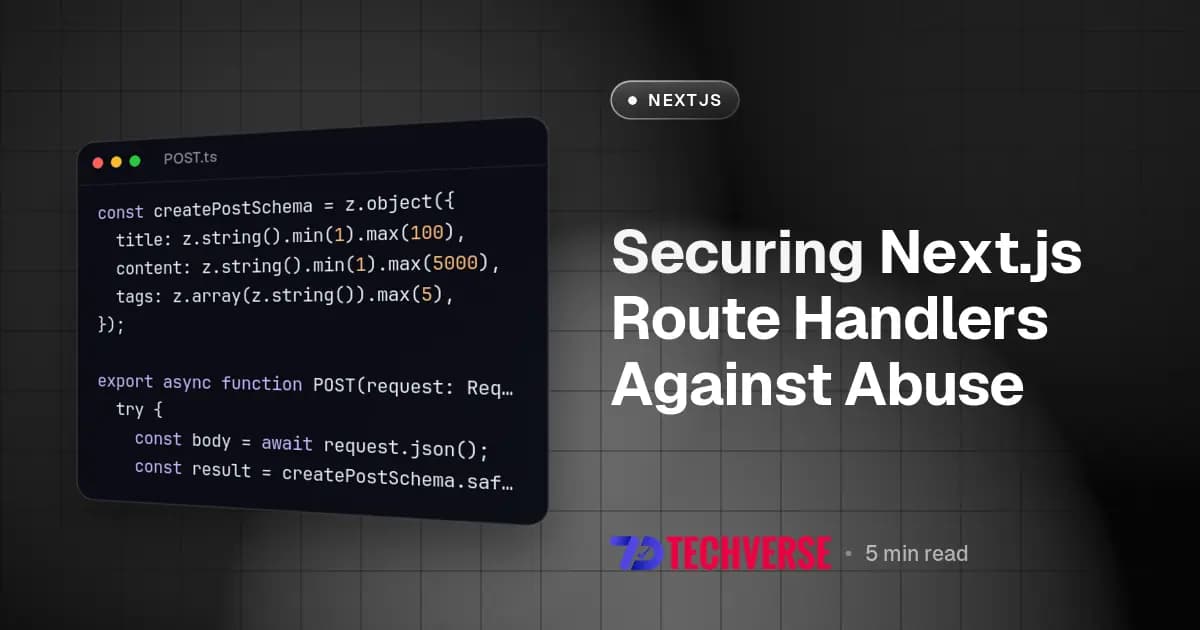
Here is how you handle incoming data inside a POST route handler by parsing the payload against a strict schema before touching any persistence layer.
import { NextResponse } from 'next/server';
import { z } from 'zod';

const createPostSchema = z.object({
  title: z.string().min(1).max(100),
  content: z.string().min(1).max(5000),
  tags: z.array(z.string()).max(5),
});

export async function POST(request: Request) {
  try {
    const body = await request.json();
    const result = createPostSchema.safeParse(body);

    if (!result.success) {
      return NextResponse.json(
        { error: 'Invalid request payload', details: result.error.format() },
        { status: 400 }
      );
    }

    const { title, content, tags } = result.data;

    return NextResponse.json({ success: true, data: { title, content, tags } }, { status: 201 });
  } catch (err) {
    return NextResponse.json(
      { error: 'Malformed JSON payload' },
      { status: 400 }
    );
  }
}
If you prefer keeping state management decoupled or if you are weighing architectural options for data mutation, you might also want to review Next.js Route Handlers vs Server Actions: The Real Boundary to decide which tool fits your specific workflow. Whenever a client sends bad JSON, request.json() throws a SyntaxError. You must catch that exception, or your server logs will fill with unhandled promise rejections that return ugly 500 pages to the client.
Beyond basic syntax errors, malicious actors frequently send deeply nested JSON payloads designed to trigger resource exhaustion or memory leaks during the parsing phase. You should configure request size limits at the infrastructure or reverse proxy level alongside your runtime validation code. Relying solely on application-level checks leaves your server vulnerable while it attempts to read massive payloads into memory before Zod even gets a chance to look at them.
Enforcing Rate Limits on Sensitive Endpoints
Validation alone won't stop a distributed script from spamming your registration or login endpoints until your database runs out of connections. You have to restrict request frequency per IP address or user identifier. Since Next.js runs across distributed edge nodes or serverless functions, you can't rely on in-memory counters unless you enjoy watching your limits reset every time a container scales down or moves to a different region.
You need an external state store like Redis to track request counts. Here is a minimal implementation using the native fetch API or an external client to enforce a sliding window rate limit inside a route handler.
import { NextResponse } from 'next/server';

const RATE_LIMIT_WINDOW = 60;
const MAX_REQUESTS = 10;

export async function GET(request: Request) {
  const ip = request.headers.get('x-forwarded-for') ?? '127.0.0.1';
  const cacheKey = `ratelimit:${ip}`;

  const currentCount = await globalThis.fetch(`https://api.redis-provider.com/get?key=${cacheKey}`, {
    headers: { Authorization: `Bearer ${process.env.REDIS_TOKEN}` },
  }).then(res => res.json()).then(data => Number(data.result ?? 0));

  if (currentCount >= MAX_REQUESTS) {
    return NextResponse.json(
      { error: 'Too many requests' },
      { status: 429, headers: { 'Retry-After': String(RATE_LIMIT_WINDOW) } }
    );
  }

  await globalThis.fetch('https://api.redis-provider.com/set', {
    method: 'POST',
    headers: {
      Authorization: `Bearer ${process.env.REDIS_TOKEN}`,
      'Content-Type': 'application/json',
    },
    body: JSON.stringify({ key: cacheKey, value: currentCount + 1, ex: RATE_LIMIT_WINDOW }),
  });

  return NextResponse.json({ success: true, remaining: MAX_REQUESTS - (currentCount + 1) });
}
Be careful with the x-forwarded-for header. If your application sits behind a reverse proxy or a Content Delivery Network that doesn't sanitize incoming headers properly, a client can spoof x-forwarded-for on every single request to bypass IP-based rate limiting entirely. Always configure your hosting provider or edge network to overwrite this header with the true socket address.
Distributed rate limiting requires careful consideration of latency. Every network call to a remote Redis instance adds milliseconds to your route handler execution time. For high-throughput public endpoints, you might need an in-memory local cache backed by periodic synchronization to Redis, trading absolute accuracy for lower response times. Don't build complex architectures until you measure where the actual bottlenecks occur in production.
Verifying Request Origins and Headers
Publicly exposed JSON endpoints often get called directly by third-party scrapers using tools like curl or custom Python scripts. If your route handler is meant exclusively to serve data back to your own frontend interface, you should verify that the request comes from an expected origin or includes custom headers that only your deployed client application generates.
Checking the origin or referer header helps block simple browser-based cross-site scripting attempts and casual scraping tools, though you must remember that these headers are trivial to forge in command-line HTTP clients. Combine origin checks with token verification or session cookies for real security.
import { NextResponse } from 'next/server';

export async function POST(request: Request) {
  const origin = request.headers.get('origin');
  const expectedOrigin = process.env.NEXT_PUBLIC_APP_URL;

  if (!origin || origin !== expectedOrigin) {
    return NextResponse.json(
      { error: 'Forbidden origin' },
      { status: 403 }
    );
  }

  const customHeader = request.headers.get('x-app-client-token');
  if (customHeader !== process.env.INTERNAL_CLIENT_SECRET) {
    return NextResponse.json(
      { error: 'Invalid client token' },
      { status: 401 }
    );
  }

  return NextResponse.json({ status: 'authorized' });
}
Relying solely on client headers leaves backend systems exposed if attackers reverse-engineer your frontend bundle to extract secret values. If your application handles sensitive mutations, make sure you pair these transport-level checks with robust authentication checks and database-level authorization rules. Protecting your endpoints requires layers, and removing any single layer usually invites the exact failure mode you were trying to prevent.
Code organization also matters when scaling these security checks across dozens of endpoints. Writing custom validation and rate limiting logic inside every single route handler leads to copy-paste errors and forgotten constraints. You should encapsulate these checks into reusable middleware or higher-order handler functions that wrap your core business logic, ensuring consistent protection across your entire codebase without bloating individual files with repetitive boilerplate.